What DevDay Exchange showed about putting agents to work
In São Paulo, more than 500 participants, case studies from QuintoAndar and iFood, and key members of OpenAI’s global team brought scale to a conversation about creating, coordinating, and evaluating work with AI.
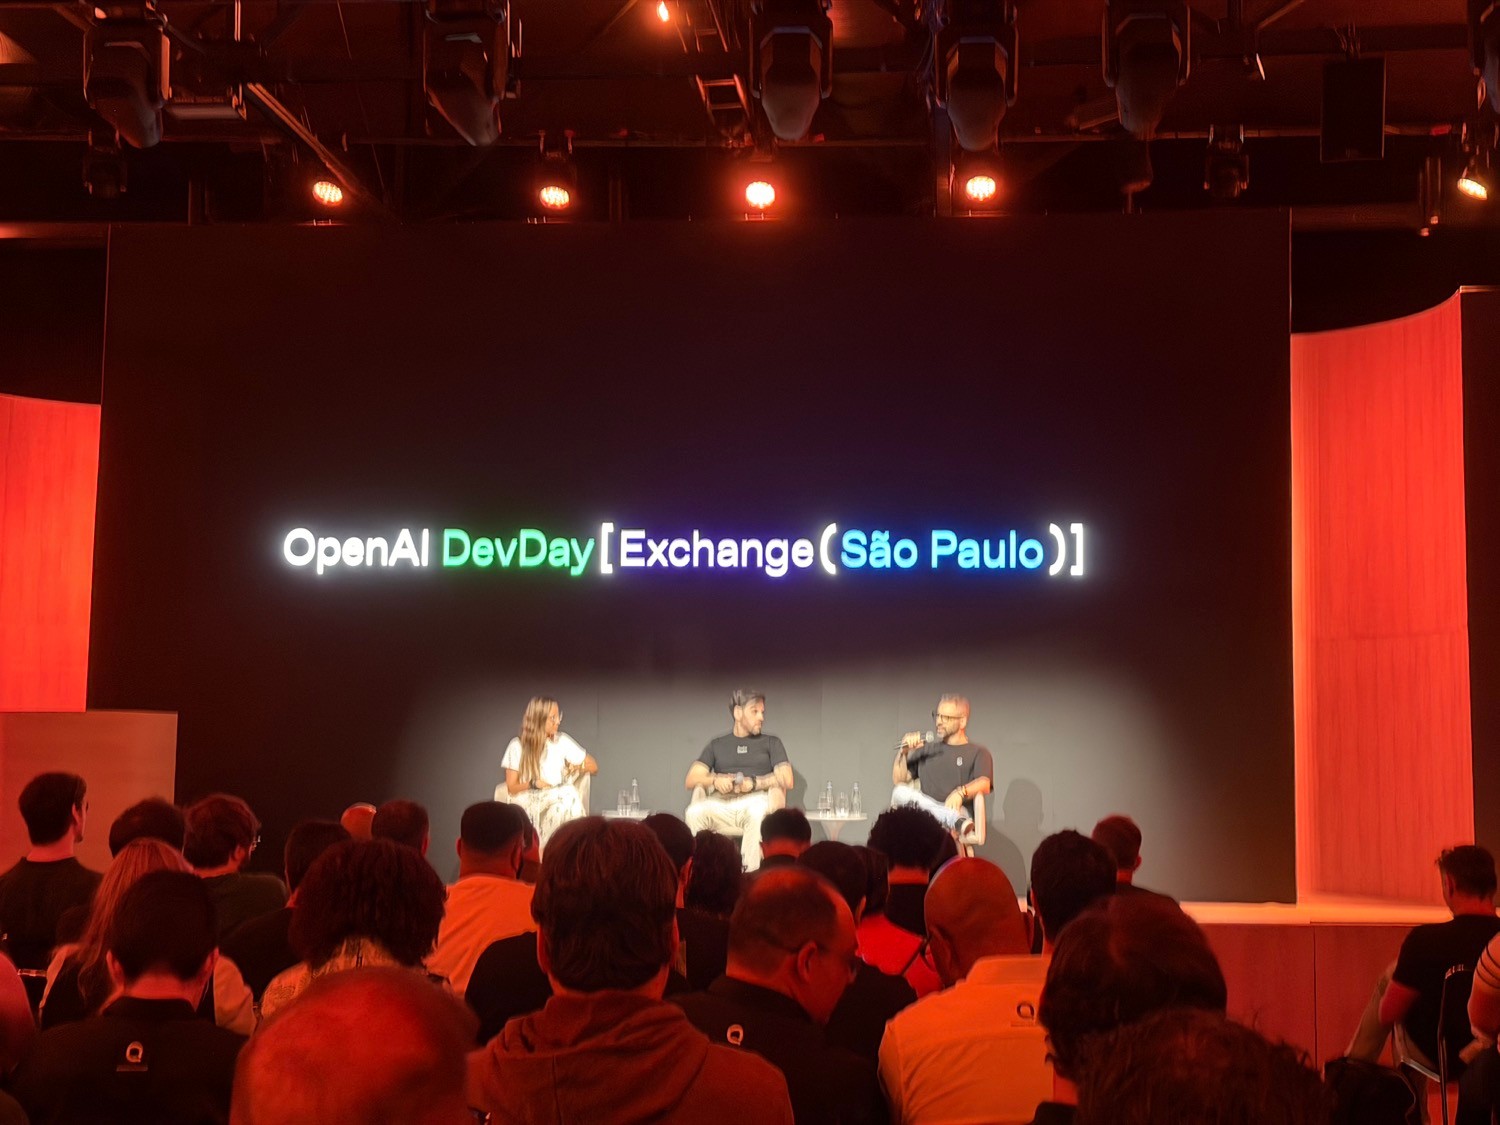
On November 6, I attended OpenAI DevDay Exchange in São Paulo. As a Codex Ambassador, I was among the 11 OpenAI ambassadors in Brazil who took part in the event. More than 500 people attended, including professionals from some of the country's largest companies, with a strong presence from OpenAI's global team.
The program combined technical sessions, demonstrations, case studies from QuintoAndar and iFood, and conversations with the company's specialists. São Paulo was one of eight cities on the international circuit, bringing developers and founders closer to the teams building OpenAI's products.
For me, the thread connecting the presentations was how to organize work as agents become capable of handling increasingly long tasks. What context do they need? How should responsibilities be divided? Who checks the delivery? And how do we trace what happened when something turns out differently than expected?
These questions already matter to people leading product, engineering, or a business function. The more AI can do, the more important it becomes to decide what is worth delegating and how to recognize a good delivery.
The work continues after the first response
One session was titled “What comes after loops?” The discussion explored the structure that keeps an agent working throughout a task.
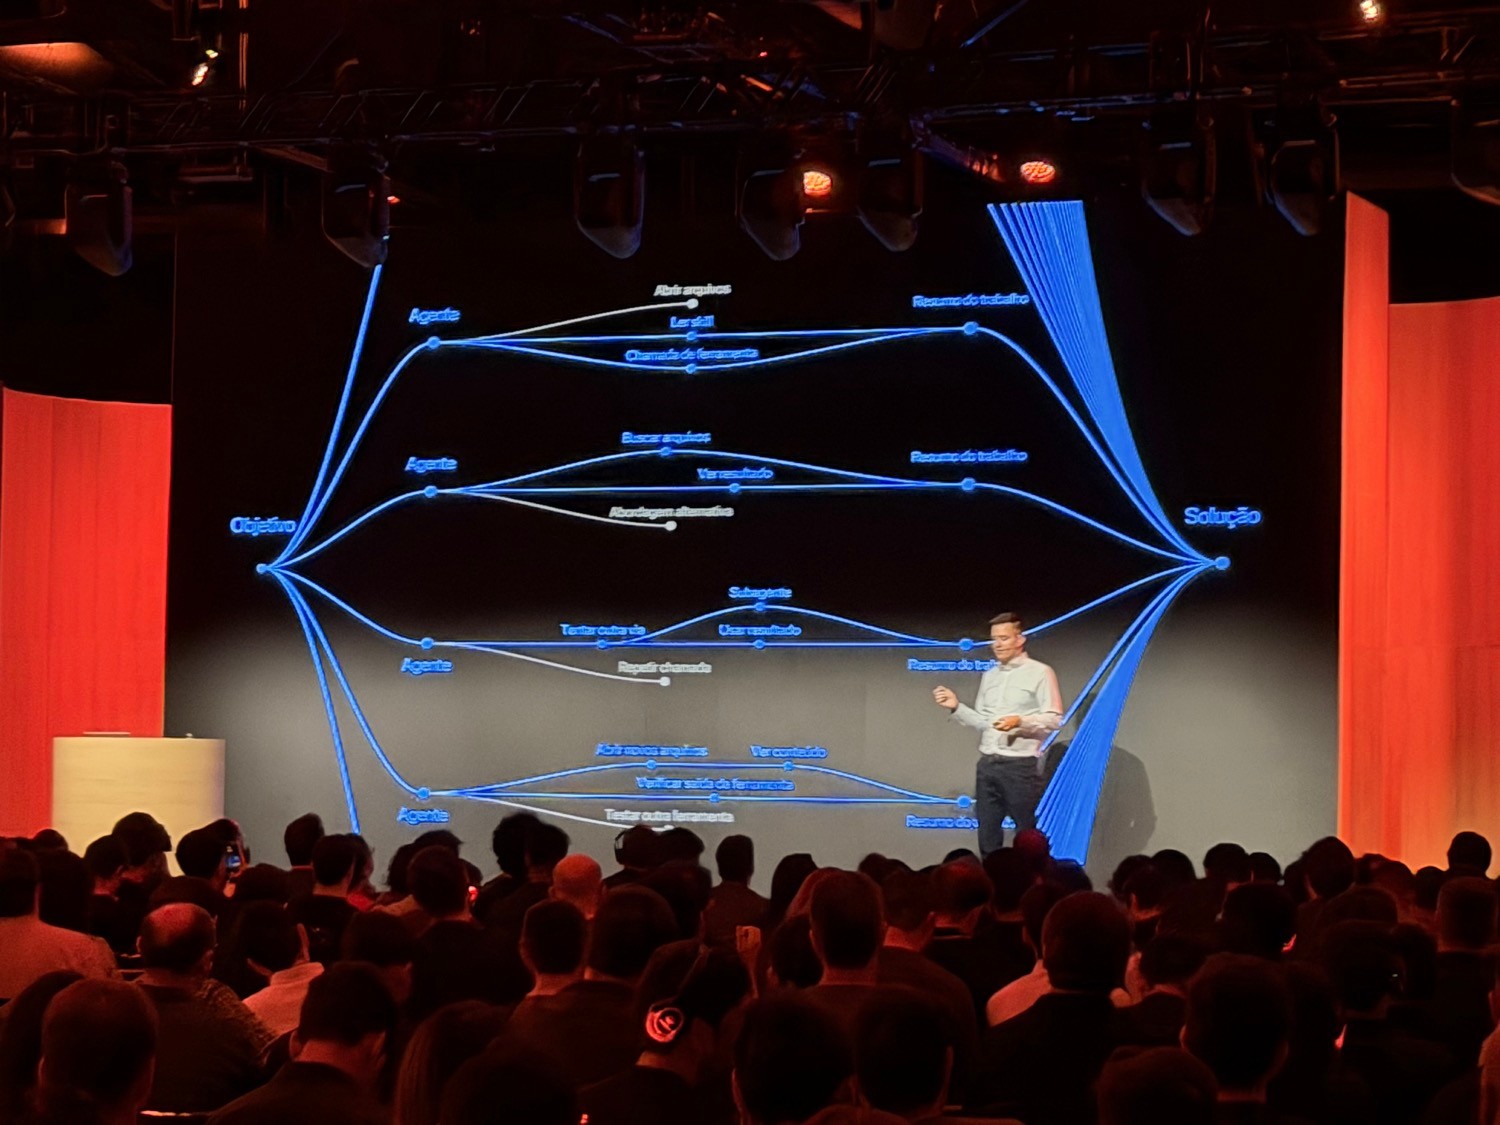
The model needs context, has to choose tools, examine results, and decide how to proceed. Along the way, it creates files, discovers constraints, and makes decisions. This set of mechanisms is commonly called a harness.
Imagine investigating a product failure. The agent checks logs, develops a hypothesis, reads the code, and runs a test. The result might rule out the initial hypothesis and require another approach. To continue, it needs to preserve what it has learned and remember which problem it was trying to solve.
A presentation can show the final outcome of that process. In day-to-day operations, what matters is being able to follow the path, deal with a blocker, and verify whether the objective was achieved.
“Harness-as-a-Service with the Agents API” was also on the program. The API, announced by OpenAI before the event, is designed to provide that managed execution layer. For builders, this makes it possible to focus more effort on the data, tools, and workflows specific to their customers.
My reading is that differentiation for an AI startup will increasingly depend on understanding this work in detail. Two companies can use the same model and deliver very different results because one understands the customer's exceptions, information sources, and completion criteria better.
A prompt can also organize a team
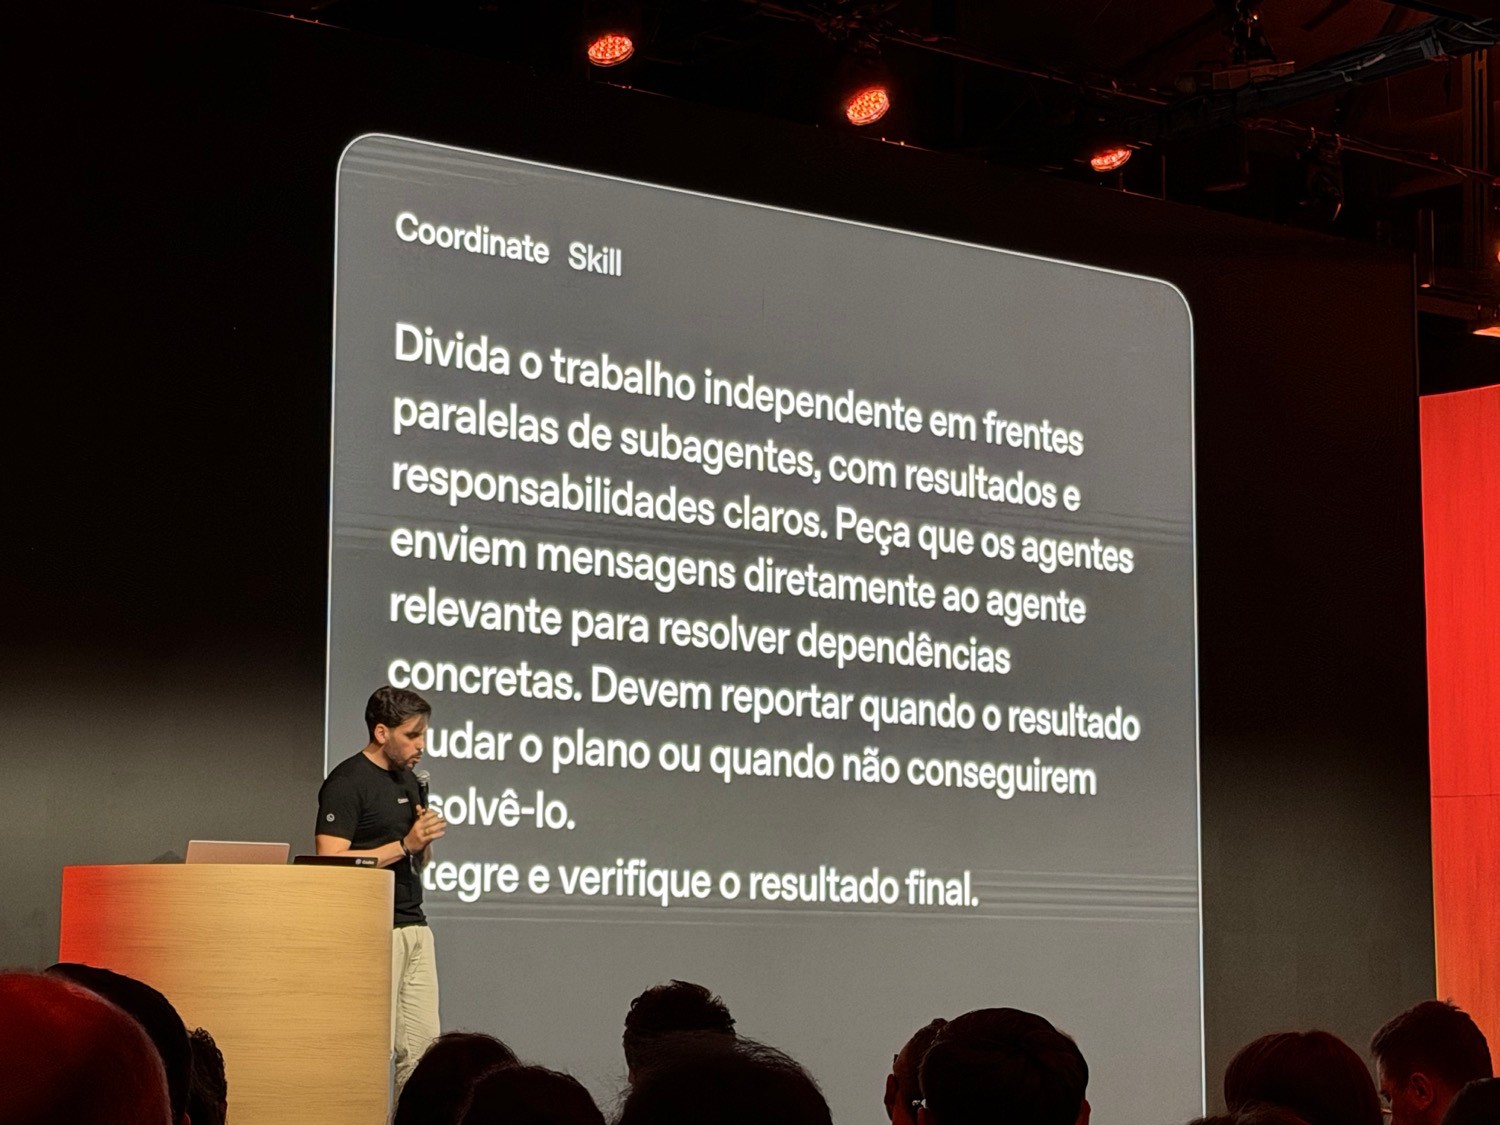
One slide that caught my attention showed instructions for dividing work among subagents. The guidance was to open independent workstreams, define outcomes and responsibilities, communicate dependencies, and integrate the delivery at the end.
This kind of instruction reveals a change in how we work with AI. When several workstreams run in parallel, someone needs to say how they come together.
Think of an application with one person handling the interface, another the integration, and another the tests. If the integration changes the data format and that decision never reaches the person building the interface, the pieces can be finished and still fail together. With agents, that dependency still exists.
Another slide addressed keeping a record of the goal, instructions, owners, outstanding work, and decisions. In long tasks, this record helps work resume without losing the conditions that guided the initial choices.
This connects with something I have been advocating in our AI activities at NewHack. Before asking for implementation, it is worth spelling out what we want to build. When execution speeds up, an ambiguous specification can create more rework in less time.
The practical consequence is to pay attention to the beginning and end of a task. At the beginning, define the outcome and constraints. At the end, check whether the solution meets what was agreed. Between those points, the agent can have room to investigate and propose approaches.
The next application might start in a spreadsheet
In the session on Sites and the next generation of web applications, a demonstration started with a spreadsheet to create an application for tracking launches. The request included an existing visual system, milestones, filters, and different ways of viewing the work.
It is a familiar example for many companies. A spreadsheet holds the information, but the team needs a better experience for consulting, monitoring, and acting on it. Building that application with AI reduces the effort needed to test whether it solves the problem.
The discussion also covered applications designed to interact with agents. Some users may arrive at a service accompanied by an AI that searches for information and takes actions on their behalf.
For entrepreneurs, this expands the product questions. Alongside thinking about how a person finds a function on screen, it becomes important to consider how that function is presented to an agent, which actions it allows, and how it confirms the result. The experience needs to remain understandable and controllable throughout that journey.
Security shapes how we delegate
The program included a session on “Codex Security: from vulnerability to verified fix.” In the panel with specialists, a question brought the subject into everyday business. What controls should be in place before allowing an agent to access internal systems or change code?
One example discussed was access to a ticketing system. If the task only requires consulting tickets, the credential can be limited to read access. The discussion included testing behavior in a controlled environment, monitoring execution, and defining when a person needs to approve an action.
The value of this approach becomes clear when something goes wrong. The team needs to reconstruct which information the agent received, which tools it used, and where it made a decision that deserves review.
The panel also raised the hub and spoke model. A technical core sets standards and guides architecture, while people across different functions help identify uses and spread knowledge.
I see value in this approach because the best problems to solve are spread throughout a company. Customer support knows the customer's exceptions. Finance knows where closing the books gets stuck. Engineering understands system dependencies. Giving these people a way to experiment with technical support can turn curiosity into projects the organization can track.
Brazilian case studies bring the discussion closer to home
Having QuintoAndar and iFood in the customer sessions brought a Brazilian reference point to the event. These companies operate complex journeys, with decisions, integrations, and people spread across multiple stages.
For those in the audience, this helps formulate questions about their own businesses. Where does information get lost between two functions? Which task takes hours from someone who knows the process deeply? What can be tested without compromising operations?
The presence of key members of OpenAI’s global team also creates an opportunity to bring these difficulties to the people building the tools. Putting AI to work in Brazil has its own conditions, existing systems, and users. That feedback is part of the exchange the event is named after.
What I would take into the next project
At the warmup we held with Marcelo Okano at NewHack, the conversation already touched on what changes when implementation gets faster. DevDay Exchange gave us more material for that discussion.
I would start by choosing recurring work with an owner who can say what a good delivery means. I would record the objective, sources, and decisions that need to remain available. Then I would give the agent the tools and access needed to test that workflow.
I would measure the outcome, including review effort and exception handling. That evidence makes it possible to decide whether to expand autonomy, change the design, or try another use case.
I left the event more interested in this work of building. Choosing the problem, specifying it, experimenting, checking, and sharing what we learn. Agents' capabilities are advancing quickly. Knowing how to organize that work is a skill we can already develop.